Underdog shows off a 32MB speech model in new demo
Underdog shifted text-to-speech execution directly into the client runtime by distributing Woof as an open 31-million-parameter model taking up 31.7MB on disk.
By Dillip Chowdary • Nov 07, 2026 • Source: TechCrunch
Artificial intelligence startup Underdog released an interactive browser-based game powered by Woof, a 31.7MB frontier text-to-speech model engineered to run entirely on edge hardware without sending data to external servers, according to TechCrunch's report. The release showcases how lightweight weights can deliver audio generation directly inside standard client environments, standing in contrast to industry setups that demand centralized data center compute. Founder Sigil Wen presented the release alongside an open download for the underlying 31-million-parameter weights, framing the architecture around private, local device execution where users keep ownership of their inputs.
This report examines Underdog's technical specifications, browser deployment mechanics, edge audio capabilities, and the startup's growing suite of offline tools. The analysis is structured for software engineers, edge AI developers, and technical product leads evaluating local synthesis alternatives against hosted cloud infrastructure. Readers will find details on Woof's operational footprints, client-side execution boundaries, accompanying transcription architectures, and the roadmap guiding Underdog's localized machine learning stack.
Underdog shows off a 32MB speech model in new: what actually changed
Underdog shifted text-to-speech execution directly into the client runtime by distributing Woof as an open 31-million-parameter model taking up 31.7MB on disk. To demonstrate the system, Underdog published an interactive web demo presented as a retro-themed game featuring a virtual typewriter, a CRT computer monitor, and an interactive desk lamp with an audio click switch. Users type sentences directly onto the typewriter keyboard, prompting Woof to synthesize spoken voice responses locally inside the browser. The experience also incorporates a rotary tuner that players rotate to generate distinct varieties of music alongside synthetic speech.
The game uses an in-engine story arc cautioning players about intrusive cloud providers encroaching on the town, presenting a challenge to defeat Darkcloud to earn an invite. Beyond thematic presentation, the deployment establishes that both synthetic vocal articulation and musical generation can execute within a 32MB distribution footprint on everyday consumer machines. The public weights are available for anyone to download, marking a departure from hosted voice synthesis APIs that require persistent web access, recurring token payments, and remote execution infrastructure.
Underdog shows off a 32MB speech model in new: how it works
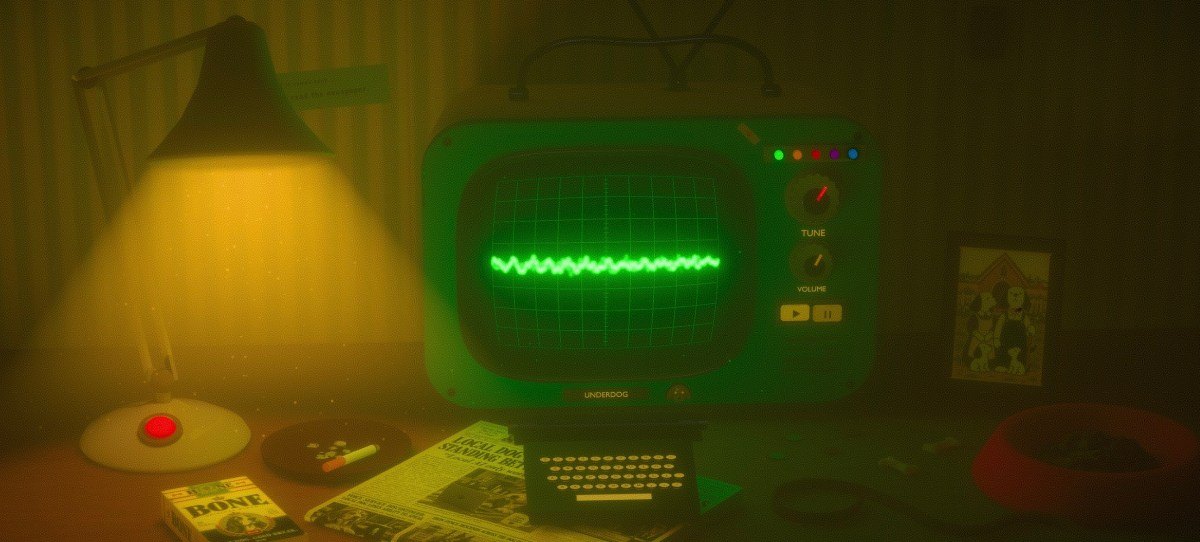
Underdog constructed Woof to operate without an active internet connection once assets load, allowing modern desktop and mobile browsers to process inference directly through local client resources. By constraining parameter size to 31 million weights, the engine computes acoustic waveforms without relying on remote server roundtrips or massive cloud graphics clusters. Users interact with input fields such as the typewriter or music tuner, and the client engine maps keystrokes and rotational settings into real-time audio output through on-device mathematical operations.
The startup pairs Woof with complementary edge models designed to handle reciprocal audio pipelines across local systems. Weeks before deploying Woof, Underdog introduced Bark, a 167MB speech-to-text model designed for client-side transcription and voice dictation. Together, these compact releases demonstrate an architecture where voice capture, natural speech transcription, and generative audio output execute within device memory boundaries, isolating user voice streams from remote network intermediaries.
Advertisement
Tech Pulse Daily
Get tomorrow's pulse first
Join engineers who read Tech Pulse before stand-up. Free, weekday mornings.
Underdog shows off a 32MB speech model in new: why it matters
Woof challenges the assumption that generative voice synthesis requires continuous connections to remote cloud data centers. Sigil Wen founded Underdog specifically to replace cloud-dependent productivity notetakers such as Granola with local systems where users retain full ownership of their data. Wen stated that he intends to train open, capable models allowing users to maintain private AI setups, projecting that standard personal devices will run today's most capable model architectures locally within months.
The approach addresses latency, hosting overhead, and privacy risks associated with transmitting raw voice streams across external networks. Operating audio generation within 32MB makes voice synthesis viable across resource-constrained devices where network connections are intermittent or entirely unavailable. While a 31-million-parameter footprint does not match the expressive range of multi-billion-parameter cloud models, it provides sufficient fidelity to handle real-time assistant responses, edge prompts, and synthetic audio feeds without infrastructure egress expenses.
Underdog shows off a 32MB speech model in new: who is affected
Software developers building offline-first applications, private notetakers, and embedded assistant interfaces gain an open acoustic model that requires no backend cloud subscriptions. Teams previously constrained by the recurring costs and privacy trade-offs of commercial voice APIs can integrate speech output into mobile apps, local desktop utilities, and browser tools. Wen highlighted that enabling users to own their data removes dependency on intrusive cloud providers that inspect or store sensitive acoustic exchanges during processing.
Enterprise users and privacy-conscious professionals handling regulated or proprietary spoken discussions gain alternatives to hosted productivity tools. By combining Woof's output generation with Underdog's Bark model for local speech-to-text transcription, organizations can run end-to-end voice processing workflows locally. Users can experiment with personalized podcast rendering, local screen readers, and interactive voice agents that operate reliably across laptops, phones, and edge endpoints regardless of network status.
Underdog shows off a 32MB speech model in new: what to watch
Underdog is expanding its ecosystem beyond lightweight voice models, having already released a 27-billion-parameter model tailored to run locally on laptops. The company is also testing a waitlisted desktop application positioned as an edge-hosted alternative to tools like Muse and Instinct, expanding its product line across local transcription, generative audio, and broader knowledge work. Tracking adoption rates across Underdog's waitlisted desktop application will show whether localized architectures can displace established hosted software in mainstream productivity environments.
Observers should watch how developer communities adapt the open 31-million-parameter weights across diverse mobile chipsets, embedded systems, and browser runtimes. The performance of Underdog's 27-billion-parameter laptop model alongside lightweight units like Woof and Bark will test Wen's timeline regarding how quickly local hardware can absorb advanced AI workloads. As developers compile and evaluate the open weights, implementations will demonstrate whether compact models can maintain stable generation quality while operating entirely detached from cloud compute grids.
Developer Action Items
- ☐ Diff the official changelog for Underdog shows off MB before you bump — APIs, defaults, and removed flags only.
- ☐ Install through the vendor's documented channel in staging; keep a one-command rollback and time-box the canary.
- ☐ Grep your repo for old flag names, lockfile pins, and plugin versions that the notes mark as breaking.
- ☐ Prefer the first patch cut over the day-zero tag unless you have a reason to be on the leading edge.
- ☐ If TechCrunch did not name a region, plan, or SKU, screenshot the official availability line before you promise it to users.
Underdog shows off a 32MB speech model in new FAQ
What is Underdog's Woof model?
Woof is an open 31.7MB text-to-speech model with 31 million parameters developed by Underdog to generate speech and music locally on edge devices and browsers.
How does the Underdog browser demo work?
The demo is a retro-themed game featuring a typewriter and music tuner that runs Woof locally in the browser, speaking back typed text and generating music without an internet connection.
What other models has Underdog released?
Underdog released Bark, a 167MB speech-to-text transcription model, alongside a 27-billion-parameter laptop model and a waitlisted application competing with Muse and Instinct.
Why did Underdog build Woof for local execution?
Founder Sigil Wen built the system to offer private, open AI models that run on personal devices, allowing users to own their data rather than sending voice inputs to cloud providers.
Sources

Author
Dillip Chowdary
Writes Tech Bytes coverage of AI, engineering, and the tools that actually ship. Editor of Tech Pulse Daily.
Related on Tech Bytes
Advertisement